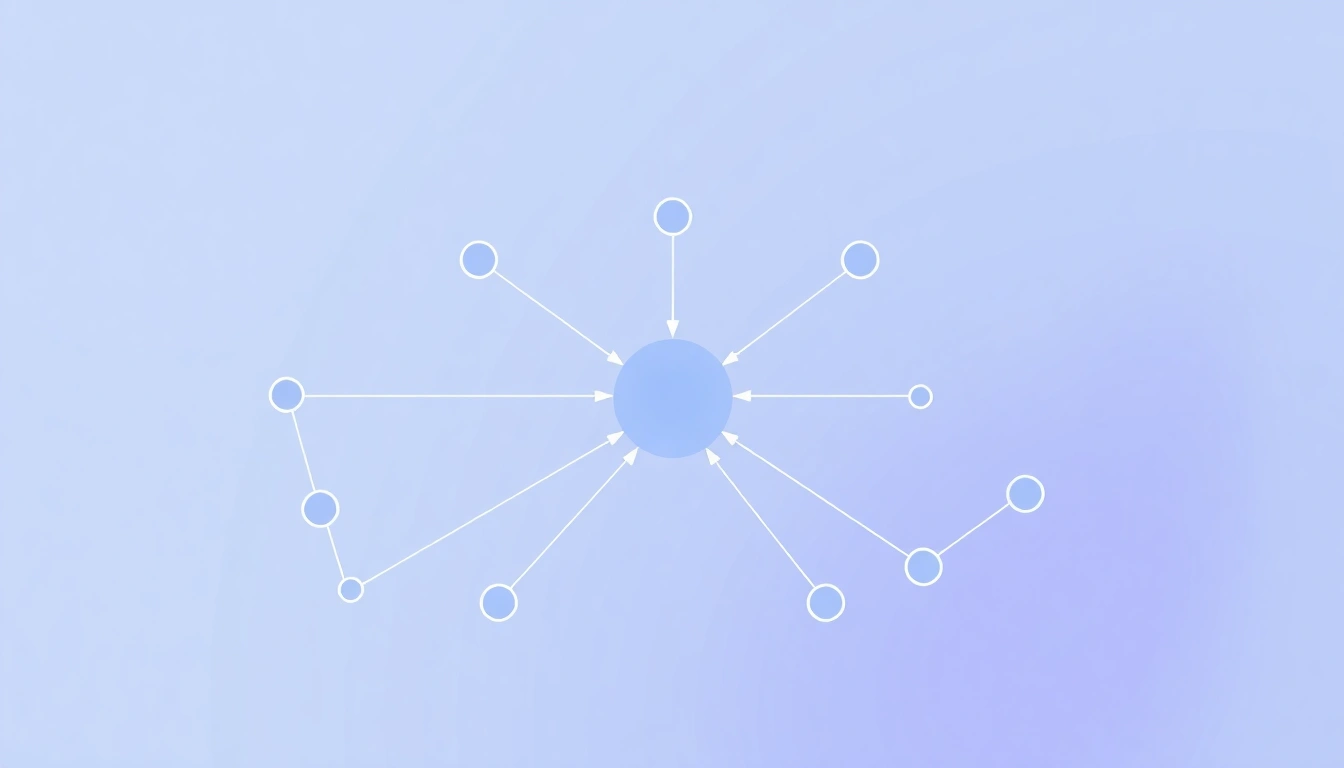
Source triangulation is the process AI engines use to verify content credibility by cross-referencing a claim against multiple independent sources. If ChatGPT, Perplexity, or Google AI Overviews finds the same fact confirmed by three or more authoritative, unrelated sources, it treats that claim as citation-worthy. Unverified or isolated claims are typically excluded.
How Source Triangulation Works Inside AI Engines
AI engines do not retrieve a single source and call it verified. They run a cross-reference pass across their training data and live retrieval indexes, comparing whether a specific factual claim appears consistently across structurally unrelated domains. A claim supported by only one source is flagged as low-confidence. Claims backed by three or more independent, authoritative sources score significantly higher in retrieval models and are far more likely to appear in a generated answer. Data from 2025 shows that 88% of Google AI summaries cited three or more sources; only 1% cited a single source (peec.ai). That ratio is not accidental. It reflects how the underlying retrieval architecture weights corroboration over singularity.
AI engines score sources using a multi-signal framework that includes domain reputation, author credentials, publication date, backlink profile, HTTPS status, structured data markup, and independent source agreement. No single signal dominates. A government database with no schema markup will still outrank a schema-heavy content farm, but a well-structured post on an established trade publication with strong backlinks and a named author will outperform both for many query types. Google's EEAT framework (Experience, Expertise, Authoritativeness, Trustworthiness) feeds directly into the source-scoring layer that determines which pages qualify as triangulation anchors. Author entity recognition, specifically whether a named author has verifiable credentials indexed across multiple platforms, is an underappreciated signal that many content teams still overlook.
What Counts as an Independent Source to an AI Engine
Independence in triangulation is not about different URLs. It is determined by IP ownership, domain registrar data, and link graph separation. Three articles published on subdomains of the same parent company are treated as a single node, not three separate confirmations. Syndicated content, where one article is republished across partner sites with identical or near-identical text, is also collapsed into a single triangulation point. Government domains (.gov), peer-reviewed journals indexed by PubMed or Semantic Scholar, and trade publications with 10 or more years of domain history rank highest as triangulation anchors. User-generated content platforms like Reddit can contribute, but only when the same claim appears consistently across hundreds of high-upvote threads. An isolated Reddit post does not triangulate a claim. Perplexity, which averages 8.2 sources per answer (everything-pr.com), achieves 94% citation accuracy in independent testing (aibusinessweekly.net) partly because its retrieval model aggressively de-duplicates correlated sources before scoring.
What Role Structured Data Plays in Triangulation Scoring
Schema markup gives AI parsers machine-readable signals about what a page is asserting, making it far easier to match claims across sources during a retrieval-augmented generation (RAG) cycle. Pages with valid JSON-LD schema are indexed and cross-referenced faster. The ClaimReview schema, originally designed for fact-checkers, is increasingly recognized by AI engines as a triangulation signal for high-stakes or contested claims. Context-graph-grounded RAG achieves up to 5x improvements in AI analyst response accuracy over raw schemas (atlan.com), which illustrates how structural signals compound retrieval precision. For businesses publishing content, this means structured data is not just a technical nicety. It is a participation requirement for triangulation eligibility.
For higher-stakes claims, the best practice is to trace citations back to the original primary source rather than citing a secondary article that references the primary. AI engines increasingly detect citation chains and penalize content that cites interpretations of data rather than the data itself. Industry data suggests a specific result, cite the study. If a government agency published a rate, cite the agency page. Secondary citations introduce a fidelity gap: the claim on your page may accurately describe the secondary article's interpretation, but that interpretation may have drifted from what the primary source actually stated.
Why Source Triangulation Matters for Your Content Strategy
Content that cannot be triangulated is effectively invisible to AI engines, regardless of its traditional SEO ranking. High domain authority, strong backlinks, and keyword density do not substitute for cross-source verifiability. Google's AI Overviews now appear on 86.7% of business-intent searches (peec.ai), and 46.5% of the URLs cited in those overviews rank outside the top 50 organically (blog.heyzeva.com). That last number is the clearest evidence that AI citation and traditional ranking are different games. A page can sit at position one in Google Search and score zero in AI triangulation if its claims are unverifiable or vague. A newer domain with lower traditional authority can earn AI citations if its content consistently makes specific, corroborated, entity-rich claims structured for machine parsing.
Trustworthy sources, from an AI engine's perspective, share five characteristics: they are real (not auto-generated or spun), relevant (topically matched to the query), authoritative (credentialed author or institutional origin), current (publication date within an acceptable recency window for the claim type), and independently corroborated (the same claim appears elsewhere without syndication). When organic click-through rates drop 61% on queries where AI Overviews appear (blog.heyzeva.com), the brands cited in those overviews earn 35% more clicks than non-cited competitors (blog.heyzeva.com). The citation gap is also a revenue gap. That is the core business case for triangulation.
At Heyzeva, we built our content architecture around this principle from the start. Every post we publish is structured to include verifiable, externally-supported claims that AI engines can cross-reference, not just keyword-optimized prose. Consider a SaaS company that publishes a proprietary benchmark report on their customer onboarding data. When third-party analysts, trade publications, and industry blogs begin citing that report, the SaaS domain transitions from a triangulation consumer to a triangulation anchor. Its claims become reference points for other content. That compounding dynamic is what separates brands that dominate AI-generated answers from brands that remain invisible to them.
How Businesses Can Engineer Content for Triangulation
Engineering for triangulation requires deliberate choices at the claim level, not just the page level. Every factual assertion should be anchored to a named, linkable source, ideally a government database, peer-reviewed study, or recognized industry report. Entity density matters: named institutions, specific dollar figures, dates, and proper nouns correlate directly with AI citation probability. Vague generalizations ("many businesses struggle with this") contribute nothing to a triangulation graph. Content that adds statistics improves AI visibility by 22% (blog.heyzeva.com), and GEO techniques more broadly can lift generative engine visibility by up to 40% (a 2024 research benchmark, peec.ai). Optimizing content with structured data markup, citation density, and statistical evidence can improve source visibility in generative engines by 15 to 41 percent (news.marketersmedia.com). The practical playbook: anchor every claim, use schema markup, publish original research when possible, and structure posts so that each section is independently extractable as a self-contained passage.
Frequently Asked Questions
How many sources does an AI engine need to triangulate a claim before citing it?
Can a small business or new domain become a triangulation anchor for AI engines?
Does source triangulation apply to local business content, or only to national and industry-level topics?
What types of content are most likely to be excluded from AI citation due to failed triangulation?
How is source triangulation different from fact-checking?
What signals do AI engines use to assess a source's credibility?
How do AI systems verify that a citation actually supports a claim?
Which types of sources do AI engines tend to trust most?
How can I fact-check citations generated by AI?
What causes AI systems to cite unreliable or outdated sources?
Sources & References
- 70+ Generative Engine Optimization (GEO) Statistics for 2026 (opens in a new tab)[industry]
- New Research Compares 12 Best Generative Engine Optimization (GEO) Service Providers in 2026 (opens in a new tab)[industry]
- AI now starts B2B vendor research, but trust still lives elsewhere (opens in a new tab)[industry]
- What Is RAG? How Retrieval-Augmented Generation Works in 2026 (opens in a new tab)[industry]
- How to Use Perplexity AI in 2026: The Complete Guide (opens in a new tab)[industry]
- The Perplexity Citation Source Index 2026: What It Cites (opens in a new tab)[industry]
- Google AI Overviews Source Selection: 2026 Guide (opens in a new tab)[industry]
About the Author
Heyzeva
AI visibility content automation platform that creates and publishes content optimized for discovery by generative AI engines like ChatGPT, Perplexity, and Google AI Overviews.
Learn more at heyzeva.com → (opens in a new tab)Related Posts
What Is Multimodal Content and Does It Help AI Engines Cite Your Blog?
Multimodal content combines text with images, video, charts, or audio in a single piece. But when it comes to AI engine citation, the relationship is more nuanced than most marketers expect. Here is what the evidence actually shows.
8 min readWhat Is Confidence Scoring and How Do AI Engines Use It to Decide Which Sources to Trust?
Confidence scoring is the internal ranking mechanism AI engines use to evaluate how much they trust a source before citing it in a generated answer. Understanding how it works is the first step to getting your content selected. This post breaks down the definition, the key signals, and what it means for your visibility.
7 min read
What Is Freshness Bias? Do AI Engines Prefer Newer Content?
Freshness bias refers to the tendency of AI engines to weight recent content more heavily when selecting sources for generated answers. But recency alone rarely wins citations. Learn how AI engines like ChatGPT and Perplexity actually balance freshness against authority, structure, and factual density.
7 min read